10 Transportation Optimization Strategies for 2026
Transportation optimization used to be a math problem.
Shave a few miles. Squeeze in more cargo. Negotiate a better rate. Call it a win. That mindset looks fine in quarterly reviews, then quietly leaks share when volatility hits. What kills you is being accountable for outcomes you weren't given the tools (or the authority) to prevent.
We've watched teams run "optimized" routes with "best-in-class" carrier rates…and still bleed money. Why? Problems traveled through email chains like a game of telephone, arriving at a desk only after they'd already cost the company money.
You've probably lived this more than once.
Optimization that will work in the future is more than a simple math exercise. It's an operating model that lets you resolve problems at your level, before they become someone else's emergency.
That means building a stack: strategy → intelligence → decisioning → execution → governance.
With that structure in mind, these 10 practices come from what consistently works in the field. This is how high-performing logistics teams stay ahead of volatility, not chase it after the damage is done.
Let’s get into it.
Before we dive into the list, let’s clarify the organizing principle.
Think of your transportation network like a living organism:
1. Strategy & network architecture is the skeleton (how you're built to move)
2. Visibility & context is the nervous system (how you sense reality)
3. Decisioning & resilience is the brain (how you decide under pressure)
4. Execution at the edge is the muscle (how you act in the real world)
5. Governance, compliance & trust is the immune system (how you survive shocks and audits)
Each best practice belongs at a specific level, and the lower levels have to be in place before the higher ones work.
Build level 3 on a shaky level 1, and you get sophisticated analysis of problems you can't actually solve, which looks great in presentations and terrible in P&L reviews.
That is why we will walk through the practices one level at a time.
|
Level |
What it solves |
Best practices |
|
"Where should we play, and how exposed are we?" |
#1, #2 |
|
"What's true right now, and why does it matter?" |
#3 |
|
"What should we do next, and how do we stress-test it?" |
#4, #5 |
|
"How do we act faster with less labor?" |
#6, #7 |
|
"Can we prove it, secure it, and price it?" |
#8, #9, #10 |
Now let's get into the transportation optimization techniques themselves.
10 Transportation Optimization Techniques for 2026
Use these transportation optimization techniques to build your stack: tighten the network, speed up decisions, and close issues before they escalate.
1. Design Your Network for Disruption, Not Just Cost

"Global optimization" in modern logistics is often a trap.
The cheapest lane on paper can be the most expensive lane in reality. Tariffs, border friction, sanctions risk, supplier concentration. They all have a way of showing up after you've committed.
We've all seen it happen. The lane passed every gate review. Then tariffs shifted, and suddenly you're firefighting a cost overrun nobody saw coming.
That’s why the best operators are moving away from a single globally optimized network and toward regionalized flows that reduce geopolitical exposure. Call it nearshoring. Call it friendshoring. The label is less important than the design principle: don’t build a network that requires stability to be profitable.
Here's what you can do to build a stable network:
- Model Total Landed Cost, Not Just Freight: Include duties, tariffs, carbon costs, inventory carrying costs, border delays, and supply chain disruption probability. Yes, all of it.
- Re-Balance Your Modal Assumptions: Nearshoring shifts you from transoceanic lanes to cross-border trucking and short-haul complexity. More stops, more appointments, more variability.
- Build Border Velocity Into Your Routing Rules: The "best route" that ignores customs throughput is the wrong route.
If you're responsible for network design, here's the scenario worth stress-testing: What happens if a key border slows by 20% for 90 days? If running that scenario requires manual work from three teams and two weeks of spreadsheet wrangling, you have a system problem. And it needs fixing before the next disruption proves it.
2. Choose Systems You Can Reconfigure Quickly
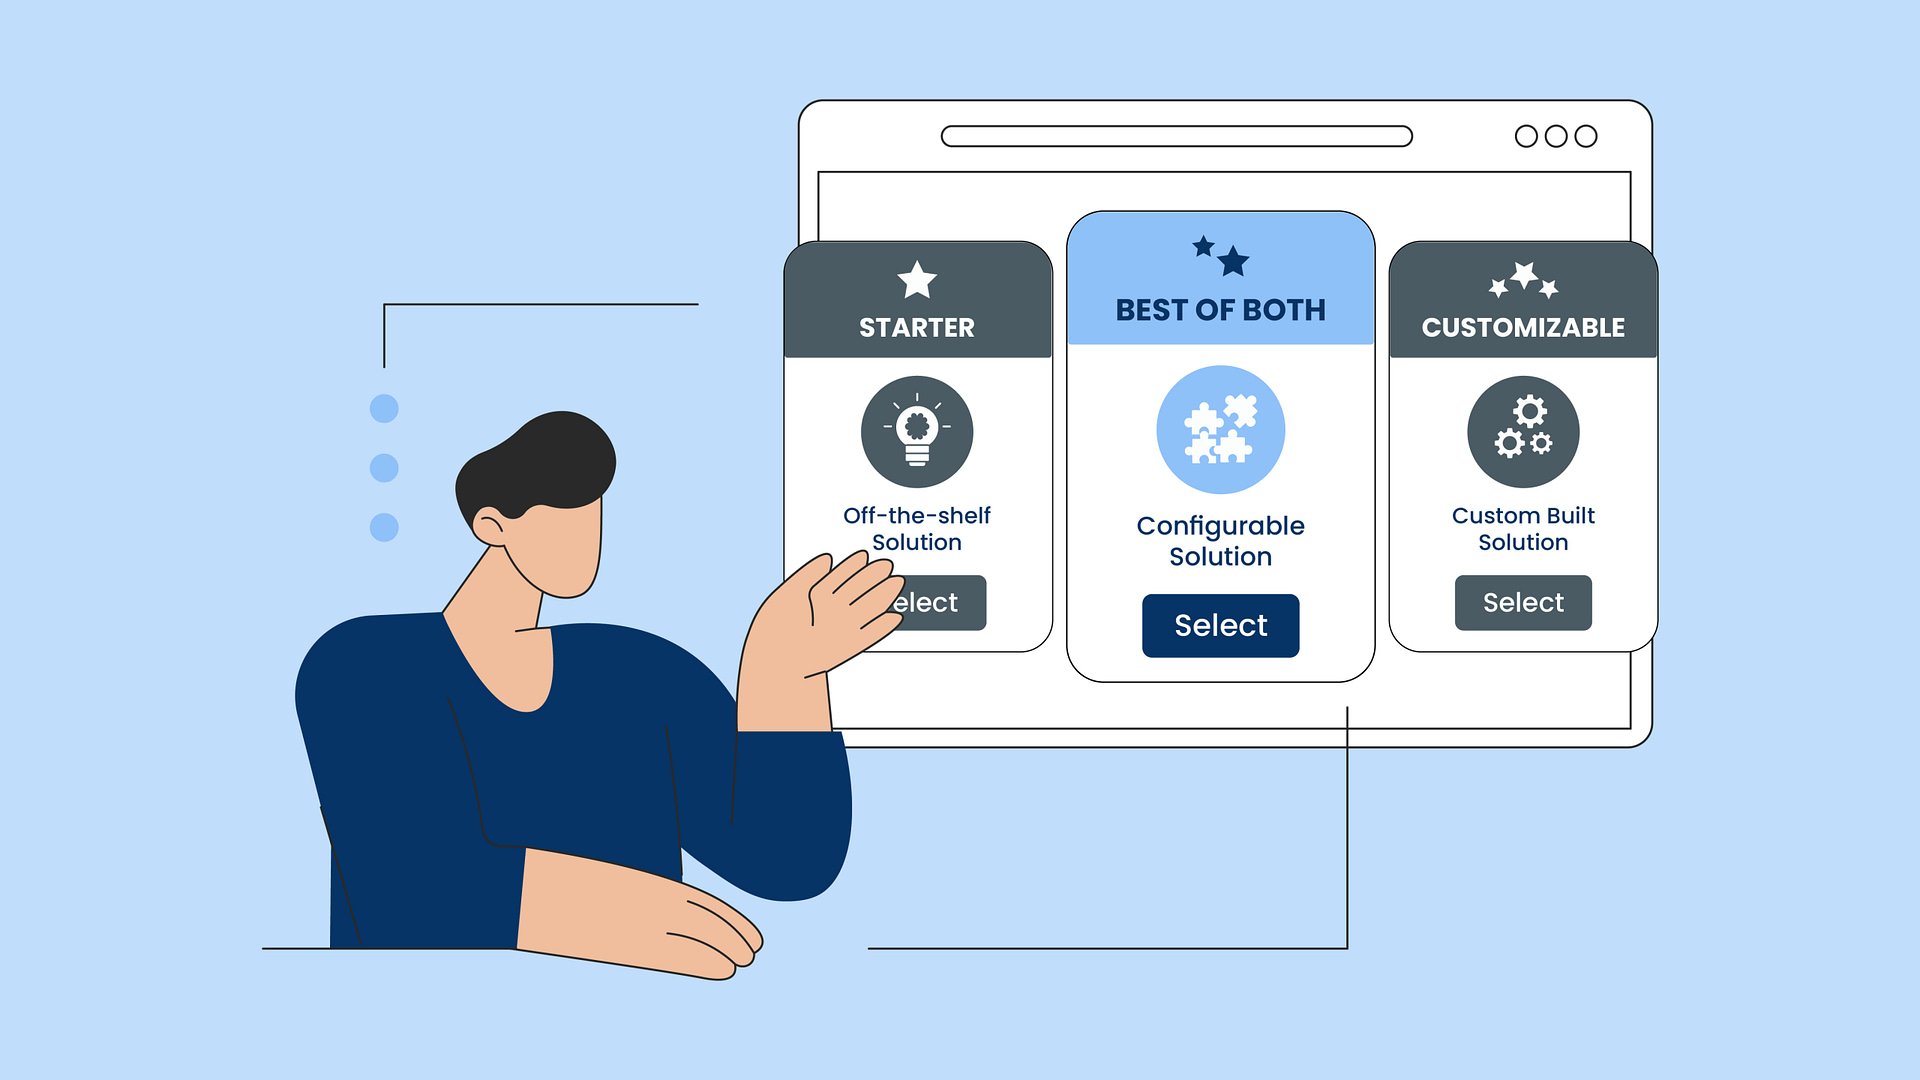
Optimization programs don't fail because of bad strategy. They fail because when reality shifts, the stack requires three committees and six months to respond.
Volatility today requires flexibility, but not the vague kind that shows up in vendor decks. Real flexibility means you can add capacity, swap modes, integrate new data sources, and adjust workflows. And you should be able to do this without turning every change into a six-month project with a dedicated Slack channel.
Here's how to build for that flexibility:
- Audit your "time-to-integrate" as a competitive KPI. Are we talking weeks or quarters? Be honest.
- Prioritize API-first connectivity over brittle file-based handoffs. Yes, EDI still works. But it shouldn't be your only option.
- Make modularity a procurement requirement. Ask vendors: "Can we replace this component without breaking execution?"
Neurored TMS & SCM is reconfigurable in a practical way: you can license and deploy only the modules you need now, and hold off on the ones you don’t. If your immediate priorities are freight rates management and supply chain visibility (but not warehousing), you don’t have to take on warehousing just to get the rest of the value. You start where the pain is, prove impact, and expand when it makes sense.
That same reconfigurability extends to the platform level. Because Neurored TMS & SCM runs on Salesforce, you’re not limited to a single vendor’s roadmap. If you need a capability that isn’t in scope yet, you can choose from 7,000+ apps on Salesforce AppExchange instead of waiting for a solution.
The outcome is straightforward: you get the best features available on the market as the market evolves, and your business benefits from competition instead of paying a lock-in tax
‣ Learn why a reconfigurable TMS beats an out-of-the-box solution
3. Build Visibility for Resolution, Not Observation
Traditional control towers made visibility the goal: "Show me where the shipment is."
That’s table stakes now.
The new goal is resolution: “Tell me what this means, what it will break, who owns it, and what options are allowed.”
One gives you dots on a map. The other gives you a decision. And honestly, we don't need more dots. We need fewer open browser tabs and faster answers.
The difference comes down to context. Your control tower needs to understand what is moving, why it matters, and which constraints apply. Customer priority. Service levels. Dwell penalties. Without that context, you're staring at a screen hoping someone notices the problem in time.
Here's how to build for resolution instead of just visibility:
- Define the Core Objects Once: Shipment, order, exception, milestone, cost-to-serve, carbon-to-serve. Get everyone speaking the same language.
- Group Exceptions by What to Do Next: "Late but recoverable." "Late and service-failing." "Cost-leaking." "Compliance-risk." Now you can route them to the right people with the right urgency.
- Tie Visibility to Action: Every exception should have an owner, a SLA, and an action path. If it doesn't, it dies in someone's inbox.
There’s one caveat to this transportation optimization strategy. Its execution only works when “see” and “do” live in the same place. If visibility sits in one tool and resolution happens in email, exceptions will stall.
Neurored’s Supply Chain Control Tower is built for multimodal visibility and exception workflows in one Salesforce view, so issues get owned and closed, not just viewed.
4. Use AI to Act Instead of Just Advise
Most teams use AI to describe what happened: delays, exceptions, status updates. It’s helpful, but it doesn’t help you change the outcome.
True transportation optimization starts when your AI can act on an approved decision within guardrails, recording what it did and why. That’s the shift from “we saw the problem early” to “the problem never reached the customer.”
That shift usually happens in stages:
- Phase 1: Augmentation. AI helps humans communicate and find info.
- Phase 2: Workflow automation. Rule-based tasks executed automatically.
- Phase 3: Cross-functional integration. AI coordinates tradeoffs across teams, balancing cost, time, and service level in real time.
- Phase 4: Strategic autonomy. AI triggers proactive moves while keeping you in the loop before you ask.
Most organizations are in Phase 1 or early Phase 2. The opportunity is building safe execution loops that move you into Phase 3.
Here's how to build those safe execution loops:
- Start With the Exceptions You See Every Day: Missed appointments, late pickups, demurrage risk. These happen constantly. Perfect for AI.
- Set the Moves AI Is Allowed to Make: Rebook, reroute, substitute carrier, split shipment. Give AI a playbook with guardrails.
- Make Every Action Auditable: Every action gets a reason code and data trail. If you can't answer "what did the system do, and why?" you don't have optimization. You have automation risk.
5. Stress-Test Your Network Weekly
Most transportation network models end up as museum exhibits. Accurate at one point in time, then left unchanged while the world moves on.
A living network model does something different. It runs continuously against current conditions, testing scenarios before they hit the real network. Capacity shifts. Congestion builds. Disruptions cascade. The model absorbs these inputs and simulates their impact in real time.
Correos Express understood this before most. With 70 facilities, 6,380 routes, and thousands of delivery points across Spain and Portugal, their express parcel network sprawled beyond what intuition could manage. Their legacy systems gave glimpses, not clarity.
So they built a digital replica of their transport network with Neurored TMS & SCM. A model that simulates operations and predicts problems before they become one. Their live performance data now flows continuously from every truck, route, and facility, feeding directly into scenarios that test decisions in a simulation. Correos Express can now see operations as they unfold and assess changes instantly.
Correos Express is an example why you shouldn’t treat modeling as a quarterly planning exercise and start running simulations weekly or daily. These simulations need to be connected to the systems that actually execute the decision.
Here's what you can do to create your living network model:
- Pick 3–5 Stress Tests That Matter: Port delay, lane capacity shock, border slowdown, carrier bankruptcy, weather region outage. You know which ones keep you up at night.
- Run Them on a Schedule: Daily or weekly. Not "when leadership asks."
- Pre-Approve Playbooks: If scenario X happens, we do Y. Get procurement and legal to sign off before the crisis happens.
Before you stress test, remember one thing: you need high-quality operational data feeding these models. That data should come directly from the systems that run the network, such as TMS execution events, carrier milestones, facility scans, and telematics. Without that, the model goes stale and the scenarios become guesswork.
6. Deploy Automation Where the Work is Predictable
Automation in freight won't arrive everywhere at once. And it doesn't need to. It pays off fastest in places where the work is repeatable, like yards, hubs, and fixed middle-mile routes. The conditions are consistent, so you can standardize the process and see results quickly.
Deploying automation matters because manual processes turn humans into bottlenecks for routine decisions. Coverage assignments. Gate check-ins. These follow clear rules, yet when your team executes them manually, their attention gets consumed by tasks that could run automatically. That leaves less capacity for the exceptions that actually demand judgment.
Here's how to build for automation that’s scalable:
- Start Where the Work is Predictable: Focus on lanes, yards, and appointment flows that look the same most days. If a location or route constantly changes, mark it as “not ready” and move on. Automation works best where the rules rarely change.
- Be Clear About When a Person Takes Over: Decide in advance which situations the system handles alone, which need approval, and which must escalate immediately. Everyone should know who owns the decision at each step, so exceptions don't stall waiting for clarity.
- Build Automation Into Daily Operations: Build automation directly into dispatch and appointment planning. Give it limits, schedules, and clear boundaries, just like drivers, docks, and equipment. If automation lives outside the plan, it stays a demo instead of becoming part of daily operations.
If your operating model assumes a permanent 1:1 ratio of human attention to moving assets, costs rise and your best people burn out faster than you can hire.
7. Design for Demand Swings, Not Heroics
Demand volatility is now the norm in logistics. Volume spikes, seasonal surges, and sudden drops are no longer exceptions, they are the operating environment. The problem is not that people cannot work harder. It is that most operations are designed for stability. When demand changes, the system does not flex. People do. And that is how burnout becomes structural.
The goal is to build operations that absorb demand swings without relying on heroics. When volume rises, the system should stretch. When it falls, it should settle back. People should not be the shock absorber.
That kind of elasticity requires three design choices that show up consistently in resilient operations:
- Control the Inflow: Deploy appointment systems that smooth arrivals, sequence docks, and eliminate the "everyone shows up at once" problem. This gives the operation a way to pace demand instead of drowning in it. You’re designing calm into the system before the work even begins.
- Do More With the Same Team: Use automation (scanning systems, AMRs, yard orchestration) as a force multiplier. These tools let you match output to demand without forcing the operation into repeated cycles of seasonal hiring and retraining. The system scales. The chaos doesn’t.
- Clear the Information Backlog: Add AI copilots for planners, dispatchers, and customer service so exceptions don’t pile up when volume spikes. This way, your operation doesn’t hinge on one person being online. You aren’t holding your breath every time someone takes PTO. The knowledge distributes and your system steadies.
When you build this way, demand swings become something the system handles, not something your team survives.
8. Treat Carbon Like a Cost Line Item
Carbon is no longer a sustainability slide. It’s becoming a procurement variable, and the compliance and cost signals are arriving faster than most teams planned for.
In the EU, shipping is under the EU ETS (Emissions Trading System). The phase-in reaches 100% of covered emissions in 2026, up from 70% in 2025. Starting in 2026, the ETS also expands to cover methane and nitrous oxide, not just CO₂.
This shift isn’t limited to Europe. In the U.S., the pressure shows up through a patchwork of state-level rules. California's fleet rules are still active. CARB scheduled a public hearing on proposed ACF/LCFS amendments for September 25, 2025. Even smaller compliance mechanics matter at scale. CARB's Clean Truck Check annual compliance fee was updated to $32.13 effective for 2026.
The question is no longer whether to track carbon. It’s how to build that tracking into daily planning before the cost shows up as a surprise. Here are three moves that make carbon a daily constraint, not a quarterly report:
- Make it Visible: Add carbon-to-serve alongside cost-to-serve metrics. Make it matter. If you can’t see it, you can’t manage it.
- Make it Part of the Decision: Put carbon exposure into mode and carrier choices at decision time, not after the fact. When a planner is choosing between options, carbon should be on the screen, next to service and cost. The decision changes when the information is there.
- Make it Part of Contracts: Include carbon clauses in your agreements. Who pays when carbon costs shift? How is it measured? What data can be verified? Sort this out now, while you still have options. Waiting until costs spike is not a strong position.
Neurored TMS & SCM enables shipment-level visibility and carbon tracking (via EcoTransIT World), so teams can monitor emissions alongside service and cost, and manage carbon as a daily metric, not just a quarterly report.
This is also where logistics stops being invisible. When carbon becomes a line item, the people who move goods become part of the climate conversation. Not as a footnote, but as decision-makers.
9. Build Traceability Before Markets Lock You Out

Digital product passports (DPPs) are moving from buzzword to compliance infrastructure. The EU's Ecodesign for Sustainable Products Regulation requires the European Commission to set up a digital product passport registry by July 19, 2026.
What's a digital product passport?
Think of it as a digital identity card for products, components, and materials. It's designed to support sustainability and compliance across the supply chain.
What’s changing is that this identity doesn’t stop at the factory gate. For logistics, this means proof is becoming part of the job. Transportation is no longer just about moving things. You have to show where those things came from and how they got here. If you can’t prove it, you may lose access to certain markets entirely.
That makes traceability something you need to run on a daily basis, not plan for later. Here’s how you can start building it:
- Know What You Have: Inventory your chain-of-custody data. Where does it live? Who owns it? How consistent is it? Be honest with yourself. You can’t fix what you haven’t mapped.
- Make it Consistent: Standardize your identifiers, such as product, batch, shipment, container, facility. If everyone is using different codes, you aren’t ready yet. Consistency isn’t optional when traceability becomes a market requirement.
- Make it Auditable: Build audit paths into your workflows. Documents, events, and exceptions should be stored against the shipment record, not scattered across email. When someone asks for proof, you need to pull it in seconds, not days.
All of this means that tools that centralize documentation and link it to shipment records (not folders) are no longer nice-to-have. When traceability determines market access, document chaos becomes a sales blocker. Not just an ops headache.
10. Secure Your Connected Systems Now
As transportation becomes more connected (through ELDs, sensors, and remote systems) the security risk grows. This is an operational issue, not just an IT one. A cyber incident doesn’t just mean fixing your systems. It means delayed freight, compromised goods, and operations grinding to a halt. We’ve seen it happen. It’s not pretty.
The reason is how most systems are designed. Optimization comes first. Security comes later. That logic creates a brittle system. Fast when calm, catastrophic under attack. Most operations bolt security on later, with add-ons, separate user stores, manual checks. Gaps surface exactly when you're under stress. That's when you can't afford them.
Security has to be built in, not added on. And there are three ways to do that:
- Segment Access: Not every device, partner, or user should see the same data or trigger the same actions. This sounds obvious but it isn't always implemented.
- Log Everything That Matters: Who changed a route? Who approved a tender? What automation executed, and why? If you can't answer these questions, you have a problem.
- Use Established Guidance to Define IoT Requirements: For example, NIST SP 800-213 explains how to identify security requirements for IoT devices and fold them into your risk management process.
The alternative is to build security into the platform from the start, not layer it on afterward. That means identity, access, and audit controls are part of the system design, not optional extensions.
A Salesforce-native TMS uses identity and access rules that are built into the platform. Permissions apply consistently, sensitive fields are protected, and critical actions are logged. You're working inside the controls, not wrapping them around the edges.
With Neurored TMS & SCM, that model maps directly to transport work. Route changes, tender approvals, and automations tie to a specific user and follow role-based controls with audit trails. And because it’s Salesforce-native, you have a security layer that never drifts out of sync.
Putting the Transportation Optimization Stack Into Practice
The game has changed. Winning isn't about the best plan. It's about who can sense reality faster, decide with confidence, and act before problems become crises. That's the stack. Build it once, and every disruption becomes less of an emergency.
The hard part isn't knowing what to build. It's finding a platform that doesn't force you to duct-tape five different tools together to get there. That's why we built Neurored TMS & SCM: multimodal visibility, exception workflows, document automation, carbon tracking, and an API-first architecture.
All Salesforce-native, all in one system. If you're ready to stop managing workarounds and start using a pre-built stack, book a demo.
Schedule your demo today!
Ricardo Medem
Share Article


Let’s Get Started
Schedule a Demo Now